Keywords: parameter estimation | statistics | machine learning
The original Zhihu question (in Chinese)
Concept map
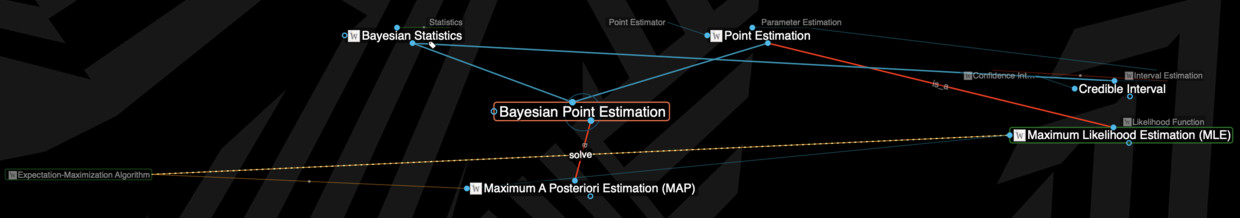
Lately I have been trying to draw concept maps of statistics in TheBrain. Seen from a fairly high level, the things in the title relate roughly as follows.
Explanation
I should still explain it roughly.
First you need the concepts of a sample and a population. If we take the population to correspond to a true distribution, then the population has the parameters needed to define that distribution. Because the population cannot be seen, we have to estimate its parameters by observing a sample (the data); this is called parameter estimation.
The result of parameter estimation can be a point (Point Estimation) or an interval (Interval Estimation). Whichever kind of estimation it is, there are many concrete methods of estimating (estimators), and different estimators express different views on what the optimal estimate is (an estimator is really a kind of objective function/model).
For example, maximum likelihood estimation (MLE) and minimum mean squared error estimation (MMSE) are both point estimators; the former uses the concept of likelihood. Maximum a posteriori estimation (MAP) is one too, except that it is an estimator from the viewpoint of Bayesian statistics/Bayesian point estimation, bringing in Bayes' theorem and the concepts of prior and posterior probability. The relationship between MLE and MAP is another matter that could be expanded on at length; I will only mention that it has to do with the prior probability and with regularization.
The expectation-maximization algorithm is a concrete algorithm that can be used to solve for MLE and MAP. It keeps producing new solutions (estimates) by iteration until it converges to the optimum defined by the estimator (it is really an optimization method).
A loose example
Parameter estimation means I want to use a sample (the heights of 1,000 Chinese people) to estimate the distribution of the heights of all Chinese people (the population). If we guess (assume) that the population follows a normal distribution, then one of the parameters to estimate is the mean μ, and another is the standard deviation σ;
point estimation means I simply guess the mean is x, and interval estimation means I guess the mean falls within some range;
MLE, MMSE, MAP and the rest are about how I think I should guess so that the average height I come up with is optimal, or what the optimal guess looks like (you can see there is no end of ways to guess: taking the sample mean, finding the mode, even picking one person's height from the sample at random all count as ways of guessing, as estimators, though many are obviously unreliable);
the EM algorithm says: once you have finished arguing about what is optimal, let's start computing with that optimum as the target. But not every definition of optimal is one that I, EM, can compute.
A further note: the two guesses above matter a great deal. They mean that being able to compute an estimate does not mean the estimate is good enough. Say we estimate the parameters of a normal distribution while the population actually follows a power-law distribution. How could we know our guess is wrong? Without more tests we actually can't, but we can at least estimate how likely we are to be wrong, and that brings in hypothesis testing.